Comment trier une liste de blogs selon leur indice de popularité Technorati? How to sort a list of blogs according to Technorati popularity index?
Dans le In the précédent article Previous Article , nous avons appris à nous servir du logiciel gratuit XScrape , qui permet d'extraire des données du web. We have learned to use the free software XScrape, which allows to extract web data. Nous allons l'utiliser aujourd'hui dans un exemple pratique : le triage d'une liste de blogs selon leur indice Technorati. We will now use a practical example: sorting a list of blogs according to Technorati index.
L'indice de popularité d'un blog, au sens de Technorati, correspond au nombre de blogs différents qui lient vers ce blog. The index of popularity of a blog, within the meaning of Technorati, is the number of different blogs that link to this blog. Ce n'est pas forcément un indice de qualité mais un indicateur de l' influence du blog dans la blogosphère, qui peut être lié aussi aux capacités de l'auteur à promouvoir son blog. This is not necessarily an indication of quality but an indicator of the influence of the blog in the blogosphere, which can also be linked to the capacity of the author to promote his blog. Il est donc logique de s'y intéresser afin d'étudier les méthodes des blogueurs qui ont réussi à faire leur trou. It is therefore logical to be interested to study methods of bloggers who have managed to make their burrows.
Pour consulter l'indice de Technorati d'un blog, rien de plus simple : il suffit de consulter la page http://www.technorati.com/blogs/{adresse_du_blog_voulu}. To view the index of Technorati blogs, nothing simpler: just visit the http://www.technorati.com/blogs/ adresse_du_blog_voulu (). En conséquence, il semble aisé d'automatiser la récupération de l'indice de Technorati de plusieurs blogs grâce à XScrape. Therefore, it seems easy to automate the recovery index Technorati for blogs with XScrape.
Afin de rendre notre entreprise intéressante, nous allons nous pencher sur la To make our company attractive, we will consider the liste de blogs de développement personnel list of personal development blogs de Priscilla Palmer (eh oui, je ne m'en lasse pas;). Priscilla Palmer (yes, I'm tired;). Le triage de la liste de Priscilla se déroulera en 4 phases distinctes : Sorting the list by Priscilla will be held in 4 phases:
- Récupération automatique des liens des blogs de la page de Priscilla Palmer AutoRecover links to blogs page Priscilla Palmer
- Transformation de ces liens en liens Technorati Transformation of these links in Technorati links
- Récupération automatique des indices Technorati de tous les blogs AutoRecover Technorati indexes all blogs
- Triage des informations obtenues Sorting information obtained
Récupération automatique des liens des blogs de la page de Priscilla Palmer AutoRecover links to blogs page Priscilla Palmer
Pour récupérer les liens des blogs de la liste de Priscilla Palmer, il suffit d'exécuter XScrape avec les paramètres suivants : To retrieve the links of blogs list by Priscilla Palmer, just run XScrape with the following parameters:
URL : http://priscillapalmer.com/pdl.php/ URL: http://priscillapalmer.com/pdl.php/
Inclusive URLs : http://priscillapalmer.com/pdl.php/ Inclusive URLs: http://priscillapalmer.com/pdl.php/
Exclusive URLs : http://priscillapalmer.com/,http://www.priscillapalmer.com/ Exclusive URLs: http://priscillapalmer.com/, http://www.priscillapalmer.com/
Regular Expression : <a[^<>]*href=”http[^<>]*target=”_blank”[^<>]*>[^<>]*</a> Regular Expression: <a href = [^<>]* "http [^<>]* target =" _blank "[^<>]*>[^<>]*</ a>
Une rapide analyse de la page de Priscilla permet en effet de voir que tous les liens des blogs listés possèdent l'attribut target=”_blank”, ce qui permet de récupérer automatiquement les bons liens. A quick analysis of Priscilla page you will actually see that all blogs listed links have the attribute target = "_blank", which automatically retrieves the correct links.
Transformation de ces liens en liens Technorati Transformation of these links in Technorati links
Après avoir récupéré le résultat de XScrape dans un fichier texte, une simple opération de remplacement suffit à obtenir les liens Technorati : After getting the result XScrape in a text file, a simple replacement operation just to get the Technorati links:
- Remplacer http:// par : http://www.technorati.com/blogs/ Replace http:// with: http://www.technorati.com/blogs/
Pour l'instant, je n'ai pas encore trouvé le moyen d'analyser une page html sans utiliser une adresse http. For now, I have not yet found a way to parse a html page without using an http address. J'ai donc mis cette page sur mon serveur local pour que XScrape puisse trouver le fichier. So I put this page on my local server for XScrape can find the file. Cela donne une adresse du genre http://localhost/ … This gives an address of type http://localhost/ ...
Récupération automatique des indices Technorati de tous les blogs AutoRecover Technorati indexes all blogs
Pour récupérer les indices de technorati des blogs de la liste de Priscilla Palmer, il suffit d'exécuter XScrape avec les paramètres suivants : To retrieve the index of blogs technorati list of Priscilla Palmer, just run XScrape with the following parameters:
URL : http://localhost/lienstechnorati.html (la page qu'on a construit à l'étape précédente) URL: http://localhost/lienstechnorati.html (the page that was built in the previous step)
Inclusive URLs : http://www.technorati.com/blogs/ Inclusive URLs: http://www.technorati.com/blogs/
Exclusive URLs : http://www.technorati.com/blogs/tag/ Exclusive URLs: http://www.technorati.com/blogs/tag/
Regular Expression : <a[^<>]*class=”links”[^<>]*href=”/search/[^<>]*title=”View[^<>]*blog[^<>]*reactions”>Authority: [^<>]*</a>[^<>]*</div>[^<>]*<div>[^<>]*<a[^<>]*class=”fav Regular Expression: <a class = [^<>]* "links "[^<>]* href =" / search /[^<>]* title = "View [^<>]* Blog [^<>] * reactions "> Authority: [^<>]*</ has >[^<>]*</ div >[^<>]*< div >[^<>]*< has [^<>]* class = "fav
Pour trouver la bonne expression régulière, il faut consulter le code source d'une page de blog Technorati. To find the correct regular expression, it must consult the source code for a Technorati blog page. Ensuite en tatônnant un peu, on obtient finalement la bonne expression régulière. Then, groping a bit, we finally obtain the proper regex.
Notons que cette méthode m'a permi de récupérer environ 80% des indices technorati, et ceci pour 3 raisons : Note that this method allowed me to recover about 80% of indices technorati, and this for 3 reasons:
1/Certains liens ne correspondaient pas à la racine du blog 1/Certains links do not correspond to the root of the blog
2/Certains liens n'ont pas encore d'indice car personne n'a encore lié à leur blog 2/Certains relationship did not index because nobody has linked to their blog
3/Certains liens ne sont pas des blogs 3/Certains links are not blogs
Triage des informations obtenues Sorting information obtained
Avec un peu d' With a bit of excel excel et un peu d' and some of autohotkey AutoHotkey , on peut faire des merveilles. , Can do wonders.
Voici comment j'ai procédé : Here's how I proceeded:
- J'ai d'abord supprimé dans la sortie obtenue toutes les données inutiles I first deleted all the resulting output data useless
-
Puis j'ai transformé le fichier en format CSV par des remplacements successifs pour obtenir des lignes où les colonnes sont séparées par des points virgule, pour pouvoir l'importer dans Excel : Then I changed the file in CSV format by successive replacements for rows where the columns are separated by semicolons, to be able to import it into Excel:
http://www.threesixtyalliance.com/360-view;6 http://www.threesixtyalliance.com/360-view; 6
http://www.todayisthatday.com/blog;314 http://www.todayisthatday.com/blog; 314
http://www.positiveselftalkguide.com;46 http://www.positiveselftalkguide.com, 46
etc. etc..
- Pour connaître les blogs dont on n'a pas pu avoir l'indice, il est intéressant aussi d'importer les données de la liste obtenue lors de l'étape 1 dans le même fichier excel afin de faire une comparaison. To find the blogs they could not take the index, it is also interesting to import list data obtained in step 1 in the same excel to make a comparison.
-
Grâce à un Through a script script autohotkey, on peut ensuite facilement faire correspondre les colonnes et obtenir un résultat de ce genre : AutoHotkey, you can then easily match the columns and get a result like this:
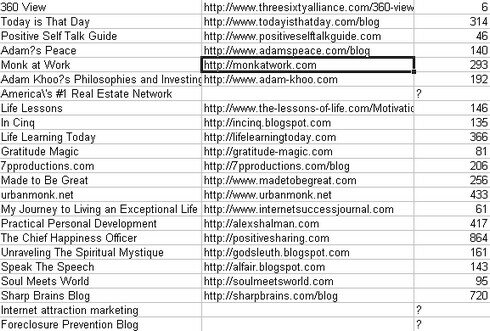
(il ya en tout 727 lignes) (there are a total 727 lines)
- On peut ensuite trier les lignes et exporter toutes ces données dans un fichier HTML pour obtenir la liste finale. We can then sort the rows and export all this data in an HTML file for the final list.
Conclusion Conclusion
J'espère que grâce à cet article, vous aurez pu découvrir la puissance de XScrape. I hope that through this article, you will have discovered the power of XScrape. On remarquera qu'il est possible de faire la même chose en utilisant l'API de Technorati, mais la méthode présentée ici a l'avantage de ne nécessiter aucune connaissance en programmation. Note that it is possible to do the same thing using the Technorati API, but the method presented here has the advantage of not requiring any programming knowledge.
Dans le prochain article, vous trouverez la liste complète des blogs de développement personnel de Priscilla Palmer triés selon leur indice Technorati. In the next section, you will find the complete list of personal development blogs Priscilla Palmer sorted according to their index Technorati.
Tags: Tags: autohotkey AutoHotkey , , blog blog , , Développement Personnel Personal Development , , Excel Excel , , expression régulière regular expression , , liste list , , parseur parser , , popularité popularity , , regular expression regular expression , , technorati technorati , , tutoriel tutorial , , xscrape xscrape
Articles similaires (en théorie) : Like (in theory):
Il ya un an sur C'éclair! A year ago on this Thread! - mars 2008 - March 2008
Stats Stats
XScrape : un logiciel gratuit pour extraire des données à partir du web XScrape: a freeware to extract data from web
Page de stats : où trouver les meilleurs scripts de statistiques Page stats: where to find the best scripts statistics
Il ya un an sur C'éclair! A year ago on this Thread! - février 2008 - February 2008



Jean Michel Jean Michel said, said,
Wrote on Wrote on mars 10, 2008 @ 20:05 March 10, 2008 @ 20:05
Un tuto bien expliqué A tutorial well explained beau travail good work
Bonne fin de journée:) Good end of day:)
Wojciech Wojciech said, said,
Wrote on Wrote on mars 28, 2009 @ 0:56 March 28, 2009 @ 0:56
Hello admin. Hello admin. Very good web site, great work and thank you for your service. Very good web site, great work and thank you for your service. for Youre a genius! for Youre a genius! spring, Thank you for your site spring, Thank you for your site